Last Updated: November 4, 2026
Quick Summary
Remote network diagnosis finds intermittent faults by monitoring the network continuously, measuring it while the symptom occurs, and narrowing the failure to one segment. Start by installing monitoring tools and building a performance baseline, then run targeted ping and traceroute tests during each reported problem.
- Collect a baseline for at least one to two weeks to capture normal daily and weekly patterns
- Run the same ping and traceroute tests from the affected device and a healthy device
- Use interface error counters, such as CRC errors, to find a bad cable or port on the failing segment
- Confirm the pattern across several tests before acting on a suspected cause
- Send timestamped, reproducible evidence when escalating to an ISP or vendor
Table of Contents
- Why Intermittent Network Problems Are Hard to Diagnose Remotely
- Step 1: Set Up Remote Network Monitoring Tools Before the Problem Returns
- Step 2: Establish a Network Performance Baseline
- Step 3: Run Targeted Ping and Traceroute Tests During Symptoms
- Step 4: Isolate Packet Loss and Identify the Failing Segment
- Step 5: Correlate Endpoint, Path and Application Evidence
- Step 6: Apply a Decision Tree to Interpret Results and Escalate Safely
- Booking a Remote Diagnostic Review With Nazca Tech
- Frequently Asked Questions
Intermittent network problems are the hardest kind to fix, and they are harder still when you cannot be in the room. A connection that drops for ten seconds every hour, or an application that stalls only at lunchtime, rarely shows up when a technician walks in to look. Remote network diagnosis is possible, but it takes a plan.
The core method is simple: watch the network over time, measure it while the symptom is happening, and narrow the failure to one segment. For more quick fixes, see common remote network problems fixed fast.
Why Intermittent Network Problems Are Hard to Diagnose Remotely
Intermittent faults disappear when you look at them. Read why remote support fails for complex networks to see exactly where remote troubleshooting stalls. A single ping test at 10 a.m. may return perfect results, while the complaint came from 3 p.m.
Remote work adds another layer. In remote network diagnosis you cannot see the cable, the switch or the Wi-Fi access point. You depend on what the software reports and what the user describes. That makes a repeatable process far more valuable than a quick guess.
- The problem is often gone by the time you test
- You lack physical access to the hardware
- User reports are vague ("it's slow sometimes")
- Multiple factors can cause the same symptom
Step 1: Set Up Remote Network Monitoring Tools Before the Problem Returns
The best time to install monitoring is before the next outage. Network monitoring tools collect data around the clock. Without that history, you are left reconstructing events from memory.
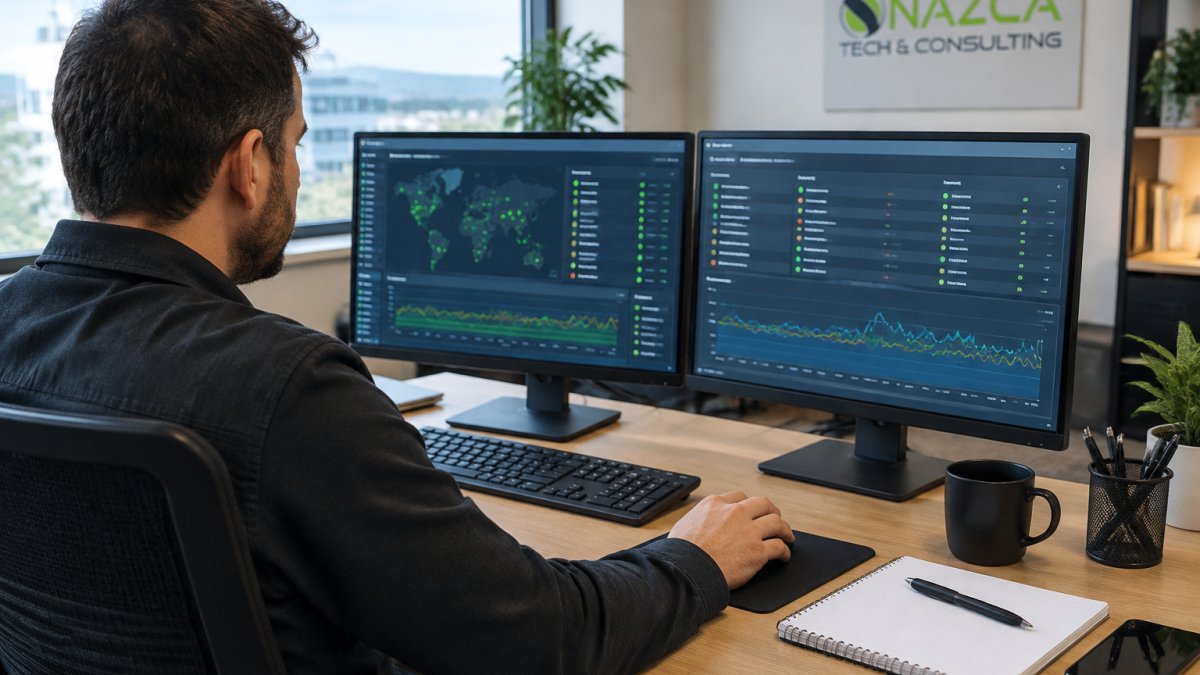
Start with the basics. Monitor your internet connection, key routers and switches, and any server or application users depend on. Explore managed network infrastructure services that provide continuous monitoring of this kind.
Before rolling monitoring out widely, confirm that your remote access to the monitored devices works and that the tool can reach them through your firewall. Test it once while the network is healthy.
Step 2: Establish a Network Performance Baseline
A baseline is a record of normal behavior, and for intermittent faults it is the single most valuable artifact you can build.
Collect data for at least one to two weeks so you capture daily and weekly patterns: business-hours load, backup windows, scheduled sync jobs, and weekend quiet periods. A window of one to two weeks is generally recommended so that a single bad day does not look like normal behavior.
Track these core metrics for each important path, and record them per target rather than as one blended number:
- Latency: average, peak, and 95th-percentile round-trip time
- Packet loss: percentage of packets that never arrive, measured over minutes not seconds
- Jitter: variation in delay between packets, which matters more than raw latency for voice and video
- DNS and HTTP success rates: whether name lookups and web requests complete, and how long they take
- Bandwidth usage: how much traffic normally flows at peak hours, and how close that is to the link's capacity
Write the baseline down as a table of normal ranges per metric and per path. Include the time of day and day of week, because a range that is normal at 2 a.m. may be abnormal at 10 a.m.
Capture the fault, not just the calm
The defining challenge of intermittent problems is that they disappear before you investigate. A baseline only helps if you also capture the symptom window.
Set alert thresholds against the baseline rather than against fixed numbers. If normal latency to a branch is 20-30 ms, alert at sustained latency above roughly twice the baseline or any packet loss above a small floor, and route the alert to a queue someone actually watches.
Watch out: a baseline collected only from a healthy device on the same subnet can hide a fault that affects one user's path.
Step 3: Run Targeted Ping and Traceroute Tests During Symptoms
When a user reports a problem, start testing immediately. Ping checks reachability and response time, while traceroute shows each network hop between the user and the destination.
Run the same tests from the affected device and from a healthy device. If only one machine struggles, the cause is more likely local, such as a bad network adapter, a host-level firewall rule or a weak wireless connection.
Record the time, the target and the results. A ping test that fails at 2:14 p.m. is far more useful than a note saying "it was slow earlier."
Step 4: Isolate Packet Loss and Identify the Failing Segment
Packet loss is one of the most common causes of intermittent trouble, and it often hides between hops. Use traceroute results to find where latency jumps or responses stop.
Once you have a suspect segment, test it more closely. Run longer ping sessions to measure loss percentages over several minutes. Check interface error counters on the switch or router that serves that link.
Watch out: do not assume the first hop with high latency is at fault. Devices that are busy with other tasks can respond slowly to test traffic even when forwarding is fine.
Step 5: Correlate Endpoint, Path and Application Evidence
A complete diagnosis rarely comes from one data source.
For example, if an application times out while the network path looks clean, check the server's load and the application logs.
Packet captures help here. When standard tools do not show the cause, a capture from the affected device during a symptom window can reveal retransmissions, resets or DNS delays that summary metrics hide.
Step 6: Apply a Decision Tree to Interpret Results and Escalate Safely
By now you have baseline data, test results and correlated evidence. The remaining job is to turn measurements into a likely cause and a next test, then hand off findings in a form someone else can reproduce. A decision tree keeps you from jumping to a fix before the evidence supports it.
Interpret the measurement before you act
- Steady latency with no loss: usually a distance or routing-path issue, or normal congestion at peak hours. Compare against the baseline before treating it as a fault.
- Latency spikes that track load: congestion or a saturated uplink. Check interface utilization and whether the spikes align with backups, sync jobs, or peak usage.
- Packet loss on one segment only: a link, port, cable, or duplex problem. Confirm with interface error counters and a longer ping run to that hop.
- Packet loss on every path at once: often the ISP or the local internet edge. Escalate with timestamps rather than changing internal equipment first.
- High jitter with low average latency: a path or queuing problem that hurts real-time traffic even when web browsing feels fine.
- Throughput below baseline but latency normal: a capacity, shaping, or application-side limit rather than a broken link.
- Application timeouts with a clean network path: look at server load, application logs, and DNS before blaming the network.
Narrow by scope
- If one device is affected and others are fine, check its adapter, drivers, local firewall, and wireless association first.
- If several devices in one area are affected, check the switch, access point, and wireless interference.
- If packet loss appears on one segment, inspect that link's cable, port, and error counters.
- If every path is affected at once, contact your internet provider with your timestamped evidence.
Change safely on a remote connection
Diagnosing remotely means the user's connection may be the thing you are about to disturb. Before any configuration change on production equipment, confirm you have out-of-band access, a separate management path, a console server, or a local contact who can power-cycle or reconnect, so a bad change does not strand the device. Schedule changes during a maintenance window, document the rollback plan first, and avoid actions that reset the interface carrying your own remote session. Respect permissions and privacy: capture only the traffic and metadata you need, and follow your organization's change-control and data-handling rules.
Escalate with reproducible evidence
When you hand off to an ISP, a network team, or a service owner, send a package they can act on without re-interviewing the user:
- The exact time window of the symptom, in a single time zone
- The test commands or probe targets used, and the interval between checks
- Baseline values versus values during the fault, per metric and per path
- The suspected segment and the evidence that points to it
- Any packet capture or log excerpt, with timestamps aligned across sources
Clear, reproducible findings get problems resolved faster by vendors and internal teams alike, and they protect you if the fault turns out to sit outside your control. Before hiring outside help, review how to choose managed IT services.
The decision tree below maps common measurement patterns to their likely meaning and the next step to take.
| Measurement pattern | Likely meaning | Next step |
|---|---|---|
| Steady latency, no loss | Distance, routing or normal peak congestion | Compare against baseline before treating as a fault |
| Latency spikes that track load | Congestion or saturated uplink | Check utilization and align spikes with backups or sync jobs |
| Loss on one segment only | Link, port, cable or duplex problem | Check error counters and run a longer ping to that hop |
| Loss on every path at once | ISP or local internet edge | Escalate to ISP with timestamped evidence |
| High jitter, low average latency | Path or queuing problem | Investigate real-time traffic paths |
| Throughput low, latency normal | Capacity, shaping or application limit | Review shaping rules and application-side limits |
| App timeouts, clean network path | Server load, app logs or DNS | Check server, application logs and DNS before blaming network |
Booking a Remote Diagnostic Review With Nazca Tech
If intermittent problems keep returning despite your best efforts, an outside review can help. Nazca Tech provides remote and on-site support, with a 1-hour response time for remote support and a 3-hour response time for on-site emergencies. For current pricing and availability, contact Nazca Tech directly or request a quote through our website.
Frequently Asked Questions
What are the most common causes of intermittent network performance issues?
Intermittent slowdowns usually come from a short list of causes: congestion on a shared link during peak hours, wireless interference on Wi-Fi, a failing cable or port that drops packets only under load, an overloaded router or switch CPU, and DNS or upstream ISP problems. Because these faults come and go, a single test rarely catches them. Continuous monitoring that records latency, packet loss and DNS response over several days shows which pattern matches the complaint, so you can focus on the right device or segment.
How can IT teams monitor network latency from a remote location?
Remote teams typically deploy a lightweight probe or monitoring agent on a site device, then schedule continuous ping or HTTP checks to key destinations such as the gateway, a cloud application and the ISP edge. The monitoring platform records round-trip time and packet loss at fixed intervals and alerts when thresholds are crossed. Reviewing those time-series logs lets you match latency spikes to specific hours, which is far more useful than a one-time speed test.
How does packet loss affect remote network performance?
Even small amounts of packet loss can noticeably degrade voice calls, video sessions and remote desktop sessions because lost packets must be retransmitted or the audio and video stutter. TCP-based applications slow down as retransmissions rise, while real-time traffic simply sounds or looks broken. Measuring loss separately from latency helps you tell whether the bottleneck is capacity or a failing link.
What are the best practices for maintaining stable remote connections?
Keep firmware current on routers and switches, separate voice and data traffic where possible, and record a performance baseline so deviations are easy to spot. Secure remote access with multifactor authentication and least-privilege accounts, and limit who can run intrusive tests. Document each diagnostic session so a later escalation to on-site staff starts with reproducible evidence rather than guesswork.